
Articles
Deep dives on sandboxes, GPU infrastructure, and stories from shipping AI to production.
NVIDIA H100 Pricing
Compare NVIDIA H100 PCIe pricing across 8 cloud providers, see what the PCIe card gives up versus SXM5, and find the cheapest way to rent one by the hour.
 Eli Mernit
NVIDIA H200 Pricing
Compare NVIDIA H200 pricing across 7 cloud providers, from single-GPU rentals to 8-GPU AWS and Azure instances, and see when its extra memory beats an H100.
Eli Mernit
NVIDIA RTX 4090 Pricing
Compare RTX 4090 cloud pricing from four providers against the 14-provider median, see who undercuts Beam, and learn when serverless beats an always-on GPU.
Eli Mernit
NVIDIA RTX 5090 Pricing
Compare RTX 5090 cloud pricing across five providers and the market median, see who undercuts Beam's on-demand rate, and learn when serverless pays off.
Eli Mernit
NVIDIA A100 Pricing
Compare NVIDIA A100 80GB cloud pricing across 8 providers, from PCIe marketplace cards to SXM4 nodes and hyperscaler VMs, and see where to rent one for less.
Eli Mernit
NVIDIA L40S Pricing
Compare NVIDIA L40S cloud pricing across 6 providers, from marketplace floors to AWS VMs, and see what the premium over an RTX 4090 or RTX 5090 buys you.
Eli Mernit
NVIDIA RTX PRO 6000 Pricing
Compare NVIDIA RTX PRO 6000 cloud pricing across 7 providers, check stock and spot options for the 96GB Blackwell card, and find where a full card costs less.
Eli Mernit
Using OpenAI-Compatible API for Open-Source LLMs
Keep your OpenAI SDK code and swap in an open model. Run vLLM on a serverless GPU with one Python object, auth built in, and scale to zero when traffic stops.
Eli Mernit
How to Run a Python Function on a Cloud GPU
Add one decorator and your Python function runs on a cloud GPU. Code syncs, billing runs per millisecond while it works, and the GPU shuts off when it returns.
Eli Mernit
GPU Cron Jobs: Run Scheduled Jobs on GPUs
Schedule GPU jobs with one cron decorator. The GPU starts when the job fires and scales to zero when it ends, so nightly runs bill by the second, not the month.
Eli Mernit
E2B vs Beam for RL Environments
Compare E2B and Beam for RL environments: GPU sandboxes, session caps, forking, and what 1,000 parallel rollouts cost on each. Pick the right fit in minutes.
Eli Mernit
Building RL Environments with Verifiers and OpenEnv
Back your verifiers or OpenEnv RL environment with a secure sandbox: gVisor isolation, GPU when the reward needs it, and rollouts that fan out to zero.
Eli Mernit
Batch Embeddings at Scale on Serverless GPU
Embed millions of documents in hours. Fan out an open-source model across GPUs with one .map() call, pay per second, skip per-token API fees.
Eli Mernit
Scaling RL Rollouts with Parallel Sandboxes
Fan out thousands of RL rollouts across isolated sandboxes from one pool. Snapshot-restore each episode, bound stragglers, and scale to zero between updates.
Eli Mernit
A Guide to Sandboxed Code Execution for RLVR Rewards
Run model-generated code as an RLVR reward: score each rollout in a gVisor sandbox with hard time and memory caps, non-zero exit fails the check.
Eli Mernit
How to Host an MCP Server and Run Tools in a Sandbox
Host an MCP server in an isolated sandbox and run its tool calls safely — public HTTPS endpoint in seconds, gVisor isolation, scale to zero. Start free.
Eli Mernit
Multi-GPU Training Without Kubernetes
Run multi-GPU training without Kubernetes: attach several GPUs to one container, launch PyTorch DDP with torchrun, scale to zero, and pay per second.
Eli Mernit
Fast Cold Starts for Serverless GPU Inference
Cut cold-start latency on serverless GPU inference: load the model once, snapshot the container, keep a warm pool. Boot in 1-3s and pay per second on Beam.
Eli Mernit
Tinker Model Pricing: What Fine-Tuning Costs in 2026
See what fine-tuning costs on Tinker, including worked cost examples and where renting GPUs gets cheaper.
 Tim Huynh
What Is a Container, Really? Five Years of GPU Infrastructure
Five years of GPU infrastructure at Beam — from ECS and Knative cold starts to a custom container runtime, FUSE lazy-loading, and a trustless binary.
 Luke Lombardi
Sandboxes for Reinforcement Learning
Run RL environments as isolated sandboxes: snapshot once, fan out thousands of parallel rollouts, and score verifiable rewards.
Tim Huynh
Hugging Face Inference Endpoints Alternatives
Compare the best Hugging Face Inference Endpoints alternatives: Beam, Modal, Replicate and Baseten. Cheaper GPUs, per-second billing and no cold-start 502s.
 Nathanael Chiang
Serverless GPU for Reinforcement Learning
Fan out thousands of RL rollouts across serverless GPUs with one .map() call. Snapshot environments, scale to zero between updates, run on your own cloud.
Tim Huynh
Batch Inference on Serverless GPU
Learn how to fan out batch inference across GPUs with one .map() call.
Tim Huynh
How to Deploy ComfyUI as an API
Turn a ComfyUI workflow into a callable HTTP API on serverless GPUs.
Nathanael Chiang
Modal Pricing Explained (2026): Plans, GPU Rates, and Why Serverless Gets Expensive at Scale
Modal's 2026 pricing, explained: full plan tiers, GPU rates, the multipliers that inflate the bill, and why serverless gets expensive at scale vs Beam.
Nathanael Chiang
ChatGPT Enterprise Pricing Guide (2026)
ChatGPT Enterprise pricing for 2026, plus every OpenAI plan: Free, Go, Plus, Pro, Business, and Enterprise. Reported per-seat costs, features, and comparisons.
Nathanael Chiang
How to Set Up GLM 5.1 for Coding Agents
GLM 5.1 explained: what Z.ai's open-weight coding model is, how its pricing compares to Claude and GPT, and how to install it into Cursor and Claude Code.
Tim Huynh
NVIDIA RTX A6000 Pricing
Compare RTX A6000 cloud pricing across five providers and the 17-provider median, check stock and spot floors, and see how it stacks up against the L40S.
Nathanael Chiang
NVIDIA B200 Pricing
Compare NVIDIA B200 pricing across 9 cloud providers, from single-GPU rentals to 8-GPU hyperscaler nodes, plus spot options and the cheapest way to rent one.
Nathanael Chiang
Best Sandbox Providers for Reinforcement Learning in 2026
Compare the best sandbox providers for reinforcement learning in 2026. Evaluate GPU support, parallelism, bring-your-own-cloud, and docker-in-docker for RL rollouts with beam.cloud.
Nathanael Chiang
How to Self-Host a Code Execution Sandbox for AI Agents (2026)
How to self-host a code execution sandbox for AI agents: isolation, orchestration, GPU, and setup — comparing Beam, E2B's infra, Daytona, and Microsandbox.
 Hassaan Qadir
E2B Pricing Explained (2026): Tiers, Limits, and Cheaper Alternatives
E2B pricing for 2026 explained: Hobby vs Pro tiers, per-second compute, session limits, and persistence costs — plus cheaper alternatives with GPU support.
Tim Huynh
Best Stateful Sandboxes for Code Execution in 2026
Compare stateful code execution sandboxes for AI agents. Explore isolation, persistence, and GPU support to find the best runtime for your agents.
Nathanael Chiang
Best Code Execution Environments for AI Agents in 2026
Compare the five best code execution environments for AI agents in 2026 — Beam, E2B, Modal, CodeSandbox, and Daytona — across isolation model, GPU access, cold-start latency, deployment flexibility, and price.
Eli Mernit
Top Daytona.io Alternatives
This guide breaks down the top alternatives to Daytona.io for sandboxed code execution.
Eli Mernit
Top AWS Lambda Alternatives in 2025
We compare five alternatives to AWS Lambda, focusing on developer-first features, pricing, performance (including cold starts), and GPU support.
Eli Mernit
Best E2B Alternatives for AI Code Sandboxes (2026)
The best E2B alternatives for AI agent sandboxes and code execution: open-source, self-hostable, GPU-ready picks like Beam and Daytona.
Nathanael Chiang
Best Alternatives to Replicate for AI Inference and Training
Engineers at startups often turn to Replicate for its simple API to run AI models, but it’s not the only developer-friendly platform on the market.
Eli Mernit
The Top Serverless GPU Providers in 2025, Ranked by Cold Start
In this article, we'll break down the top serverless GPU providers by cold start times.
Eli Mernit
How Lovable and Bolt Work: Architecture of AI App Builders
Explore the architecture behind AI app builders like Lovable and Bolt, including planning agents, sandboxes, preview servers, code generation, MCP, and deployment.
Luke Lombardi
Best ComfyUI Workflows: Templates, Examples, and Downloads
Explore the best ComfyUI workflows for image, video, audio, LoRA, inpainting, upscaling, and ControlNet, with template sources, download tips, and setup guidance.
 Leah Childers
How to Use ComfyUI
A complete guide on using ComfyUI, ranging from installation instructions to parameters and workflow optimizations.
Leah Childers
Zero Shot Prompting vs. Few-Shot Prompting: Techniques and Real-World Applications
Explore the Difference Between Zero-Shot and Few-Shot Prompting in Language Models
Nathanael Chiang
How to Install ComfyUI: Portable, Desktop, Windows, Mac, and Linux
Install ComfyUI on Windows, macOS, or Linux with portable, desktop, and manual setup options, plus system requirements, GPU notes, and common fixes.
Leah Childers
BF16 vs FP16: A Comparison of Performance and Efficiency
Discover how FP16 and BF16 influence deep learning performance
Nathanael Chiang
Choosing the Best Embedding Models for RAG and Document Understanding
Explore the different embedding models used in Retrieval-Augmented Generation (RAG), and learn how to choose the best one for your application.
Nathanael Chiang
The Best OCR Models in 2025
Explore the best OCR models for different use cases.
Leah Childers
Top Heroku Alternatives
Modern PaaS solutions similar to Heroku that may better suit your use case.
 Samuel Liu
The Best Open Source Text to Speech Models for Developers in 2025
Exploring the best open source TTS models and different use cases.
Leah Childers
LLM Parameters: A Comprehensive Guide for Developers
Learn about how to customize LLMs for specialized use
Leah Childers
Zonos TTS: A Text-to-Speech Alternative to ElevenLabs
Deploying Zonos with Beam
 Mia Gouffray
Unsloth: A Fine-Tuning Guide for Developers
Fine-tuning Meta LLAMA 3.1B LLM with Unsloth
Mia Gouffray
Understanding Qwen 2.5: Features, Benefits, and Practical Applications
Learn about Qwen 2.5, one of the top LLMs available today.
Nathanael Chiang
The Best LLM for Coding: A Comprehensive Guide for Developers
Exploring the top LLMs for different use cases and metrics for evaluation.
Samuel Liu
CUDA Cores vs. Tensor Cores
Explore the roles of CUDA and Tensor cores in modern GPUs, their impact on machine learning, graphics rendering, and parallel computing, and how they work together to optimize performance.
Nathanael Chiang
Mochi 1: The Top Open Source Video Generation Tool You Need to Try
Mochi-1 is a powerful model for generating high-quality videos based on text prompts.
Mia Gouffray
FP8 vs. FP16: Choosing the Right Precision for Deep Learning
Discover how FP8 and FP16 precision formats impact deep learning models, balancing memory, speed, and accuracy for optimal model performance.
Nathanael Chiang
Maximizing LLM Efficiency with SGLang
A high-level introduction of SGLang and its features, capabilities, and use cases.
Samuel Liu
Fast Text-to-Speech Inference with Parler TTS
Parler TTS is a lightweight model that generates high quality, natural sounding audio from your text. In this article, we'll dive into how it works!
Mia Gouffray
Using FASTQC: A Guide to Quality Control in High-Throughput Sequencing
We'll dive into what FASTQC is, how to use it, and how to interpret its results.
Eli Mernit
How Goblins Cut Inference Time by 50%
Learn how Goblins used Beam's 4090s to cut their inference time in half.
Eli Mernit
How to Use Docker Prune
Learn to use Docker Prune to remove unused resources from your Docker environment.
Eli Mernit
Top 5 AI Hosting Platforms
In this article, we'll explore the most popular hosting platforms for your AI applications.
Eli Mernit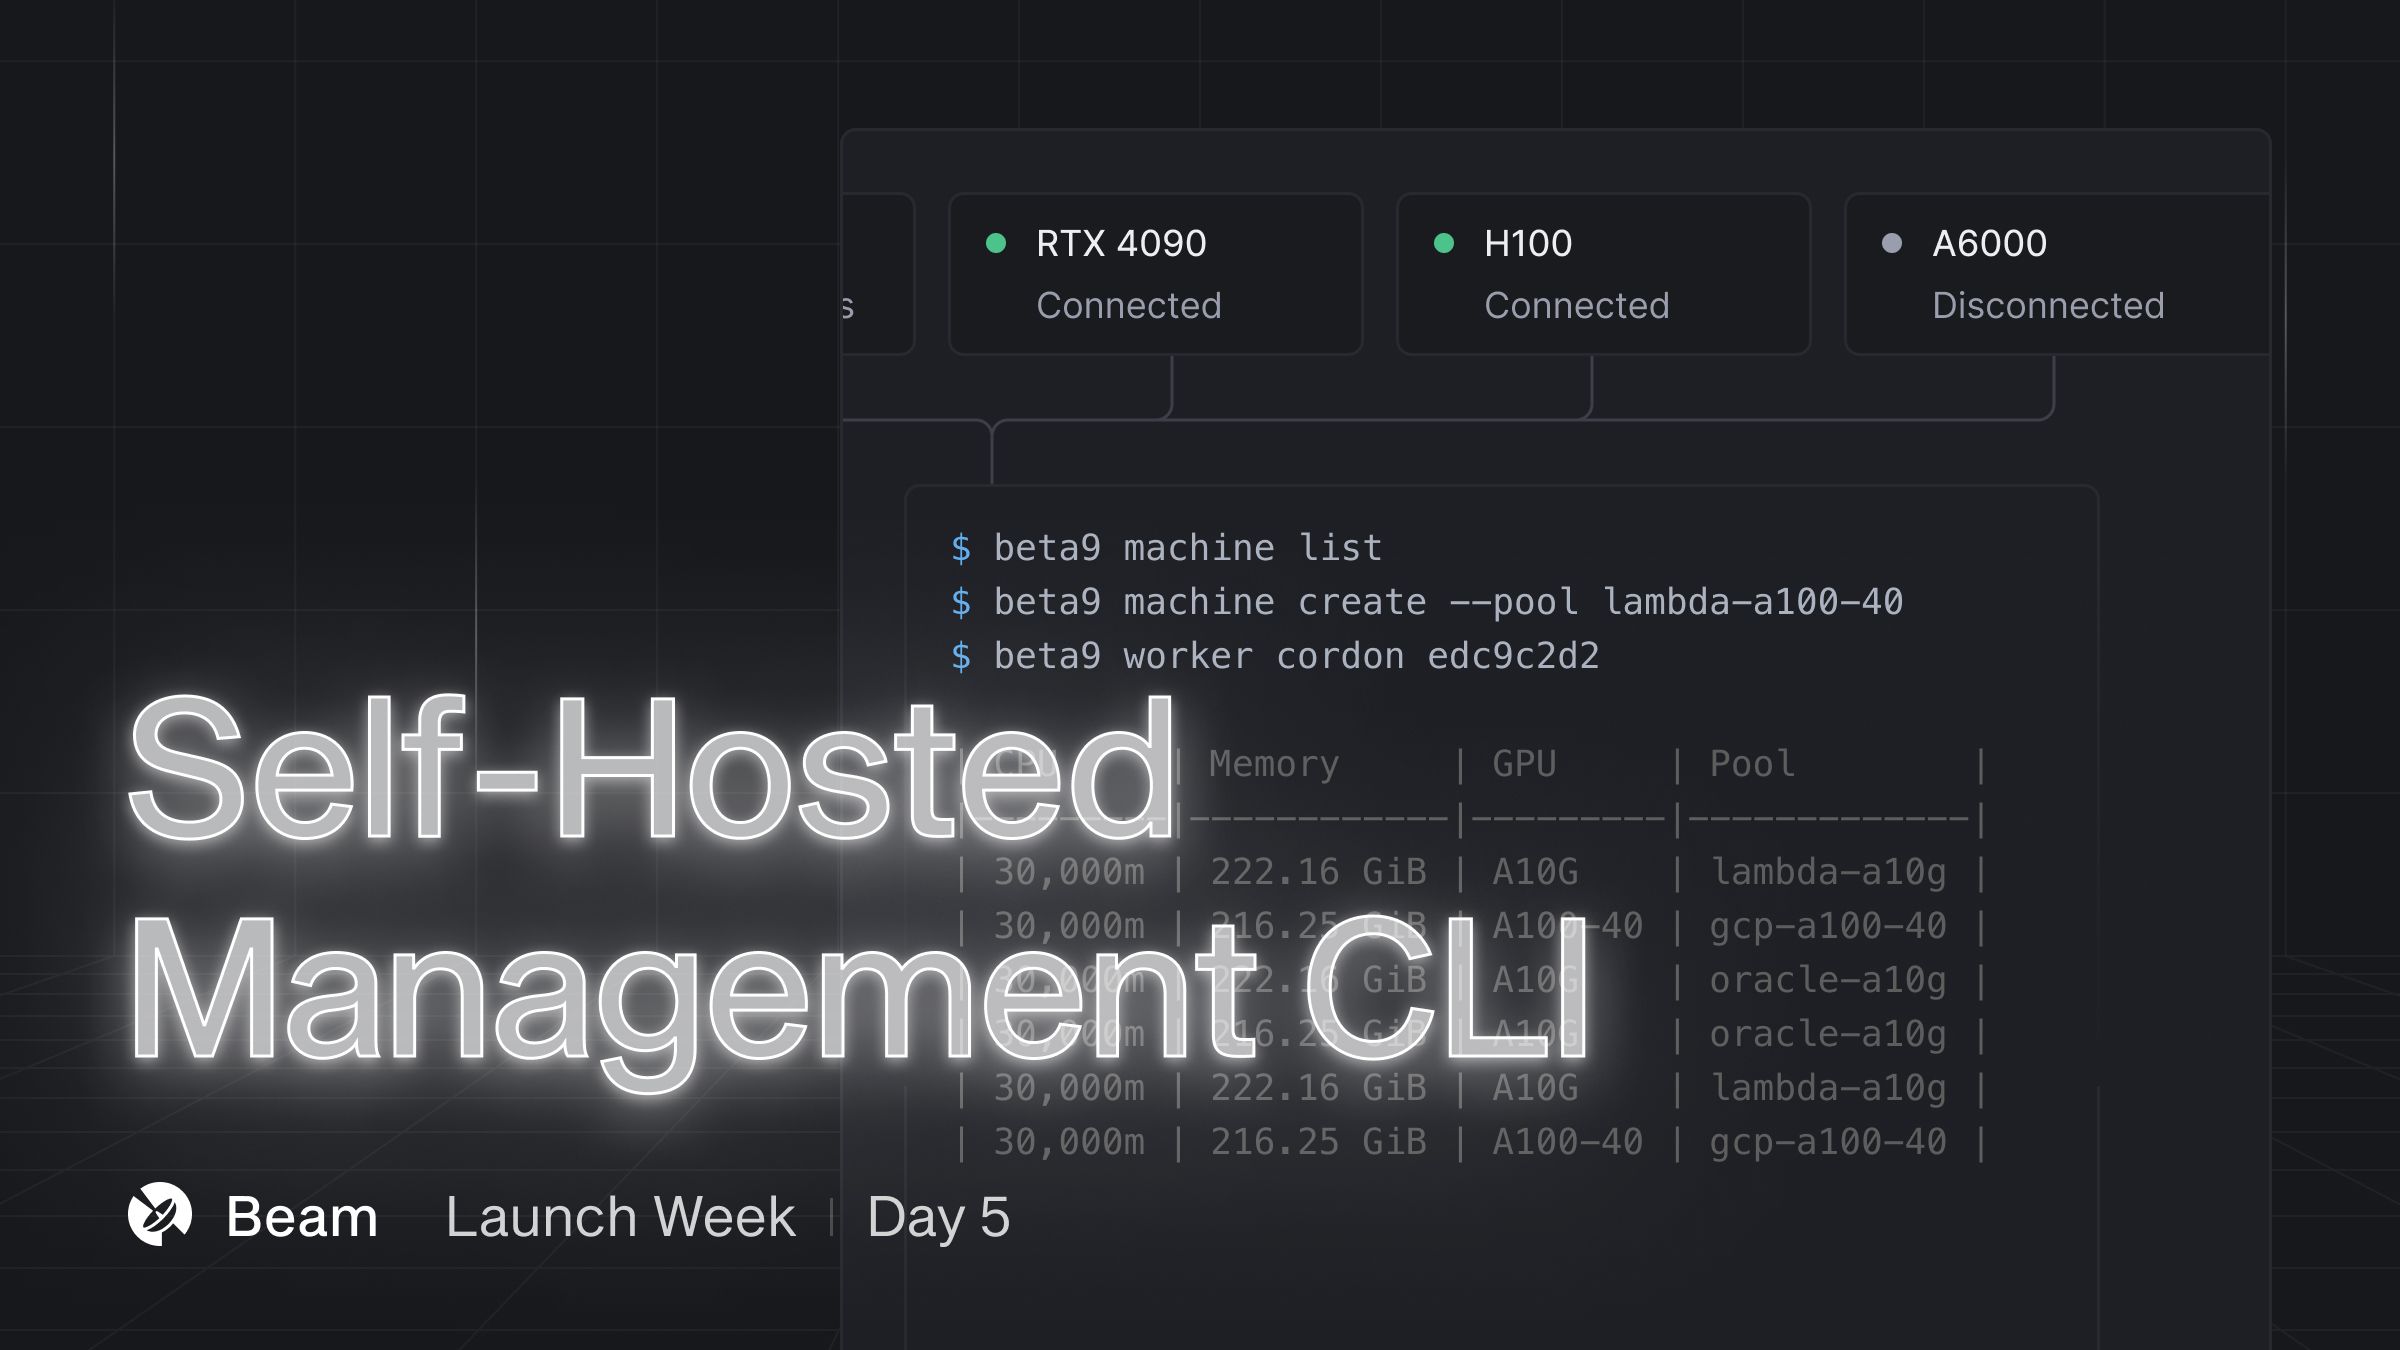
How to Manage Your GPU Cluster
We're releasing a new CLI to manage your GPUs when self-hosting Beta9.
Eli Mernit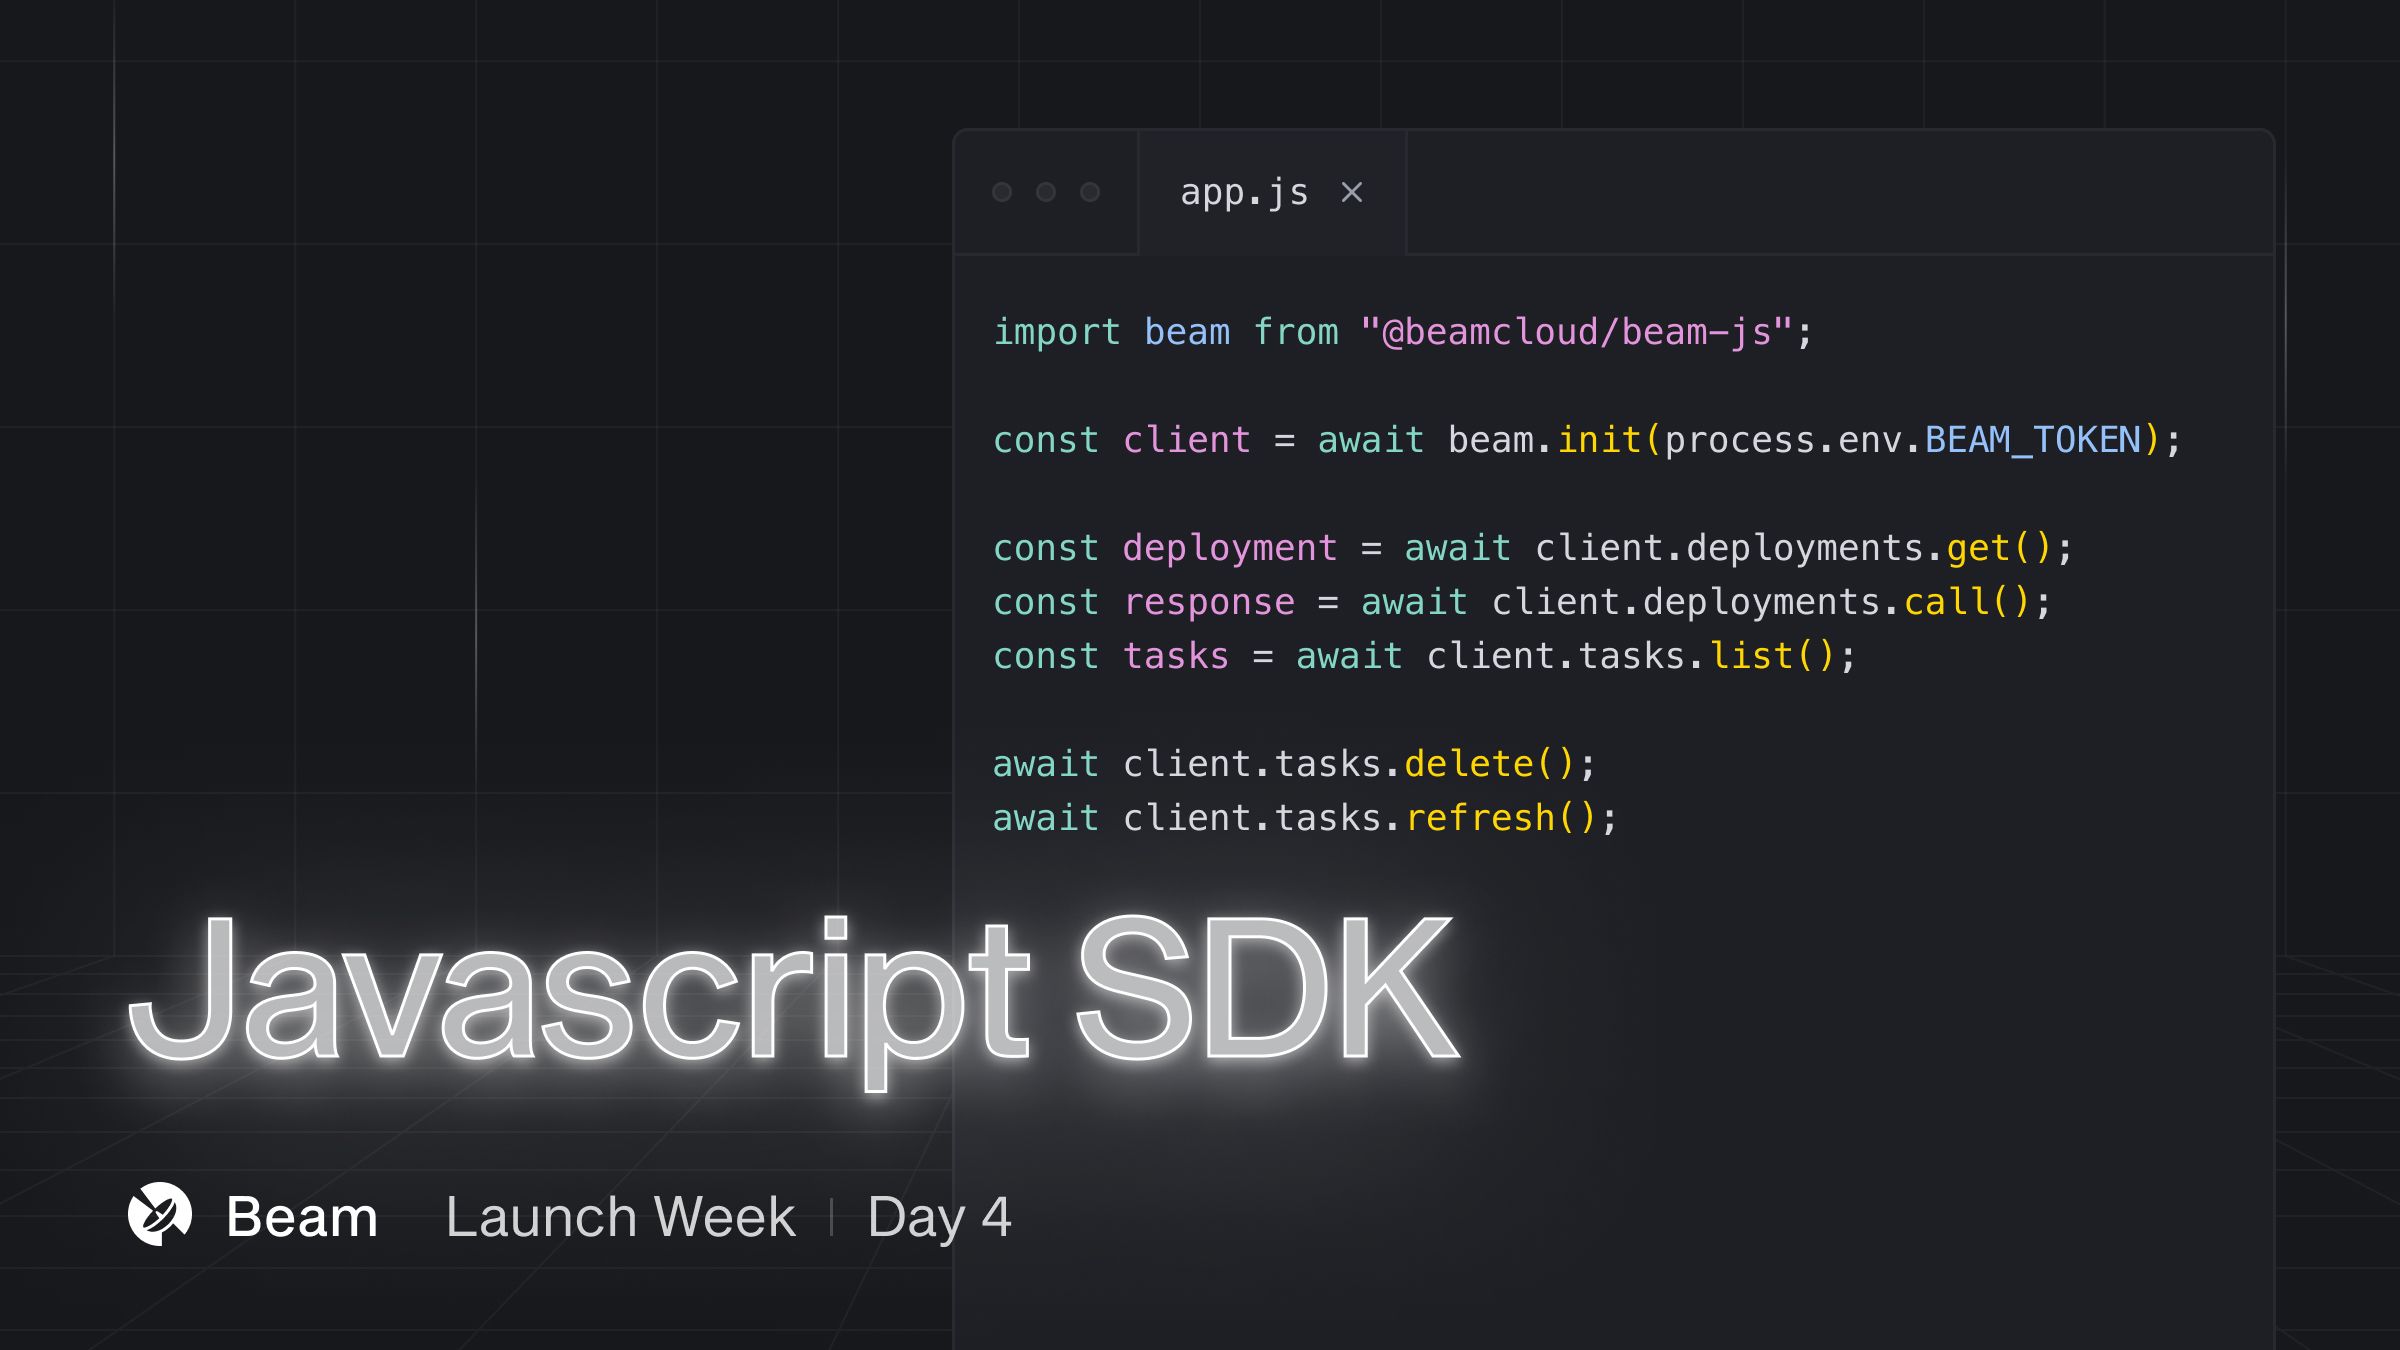
Introducing: Beam Javascript SDK
We've shipped a Javascript SDK, making it easy to manage Beam apps from your client.
Eli Mernit
Petri Nets as an Agent Architecture
We're launching the first agent framework built for concurrency and synchronization.
Eli Mernit
Deploying LLMs with Streaming Responses
Build real-time streaming apps with Beam.
Eli Mernit
Serving vLLM for LLM Inference
We just shipped a new feature that makes it easy to host serverless vLLM apps.
Eli Mernit
Top Google Colab Alternatives
Explore different Jupyter Notebook Cloud IDEs for data science and ML.
Eli Mernit
Top Python Hosting Platforms
Discover modern hosting platforms for running Python apps on the cloud.
Eli Mernit
How We Add GPU Capacity at Beam
Learn how we add GPUs to our cluster using Beta9, our open source compute orchestrator.
Eli Mernit
RTX 4090 Price: MSRP, Current Cost, and Cloud GPU Rental
See RTX 4090 MSRP, current market pricing, cloud GPU rental costs, and when it makes more sense to buy a 4090 versus renting GPU compute.
Eli Mernit
WhisperX Tutorial: Install, Diarization, API Server, and Cloud Deployment
Learn how to use WhisperX for fast transcription, word-level timestamps, alignment, speaker diarization, API serving, and cloud GPU deployment.
Hassaan Qadir
Top Python Web Frameworks: Flask, Django, and FastAPI
Explore the differences between the three most popular Python web frameworks.
Hassaan Qadir
Fine-Tuning Llama 3 and Deploying It for Inference
Learn how to fine-tune Llama3 and serve it as an inference API
Hassaan Qadir
Building a Modern Serverless Cloud for Bioinformatics
Today, the cloud feels a bit like programming with punch cards. And we think there's a better way.
Eli Mernit
How Gepetto Achieved Faster Cold Starts While Cutting Infrastructure Costs
When Simon Brami discovered Beam, he was looking for a solution that would offer fast boot times, reliability, and predictable pricing.
Eli Mernit
How Geospy Scaled to 3,000,000 Inference Requests in 1 Month With Beam
Learn how GeoSpy uses Beam to serve millions of inference requests to their customers.
 Daniel Heinen
The Magic of Serverless GPU: A Behind the Scenes Look
Pay-per-use GPUs seem like magic, but here's how it actually works behind the scenes.
Eli Mernit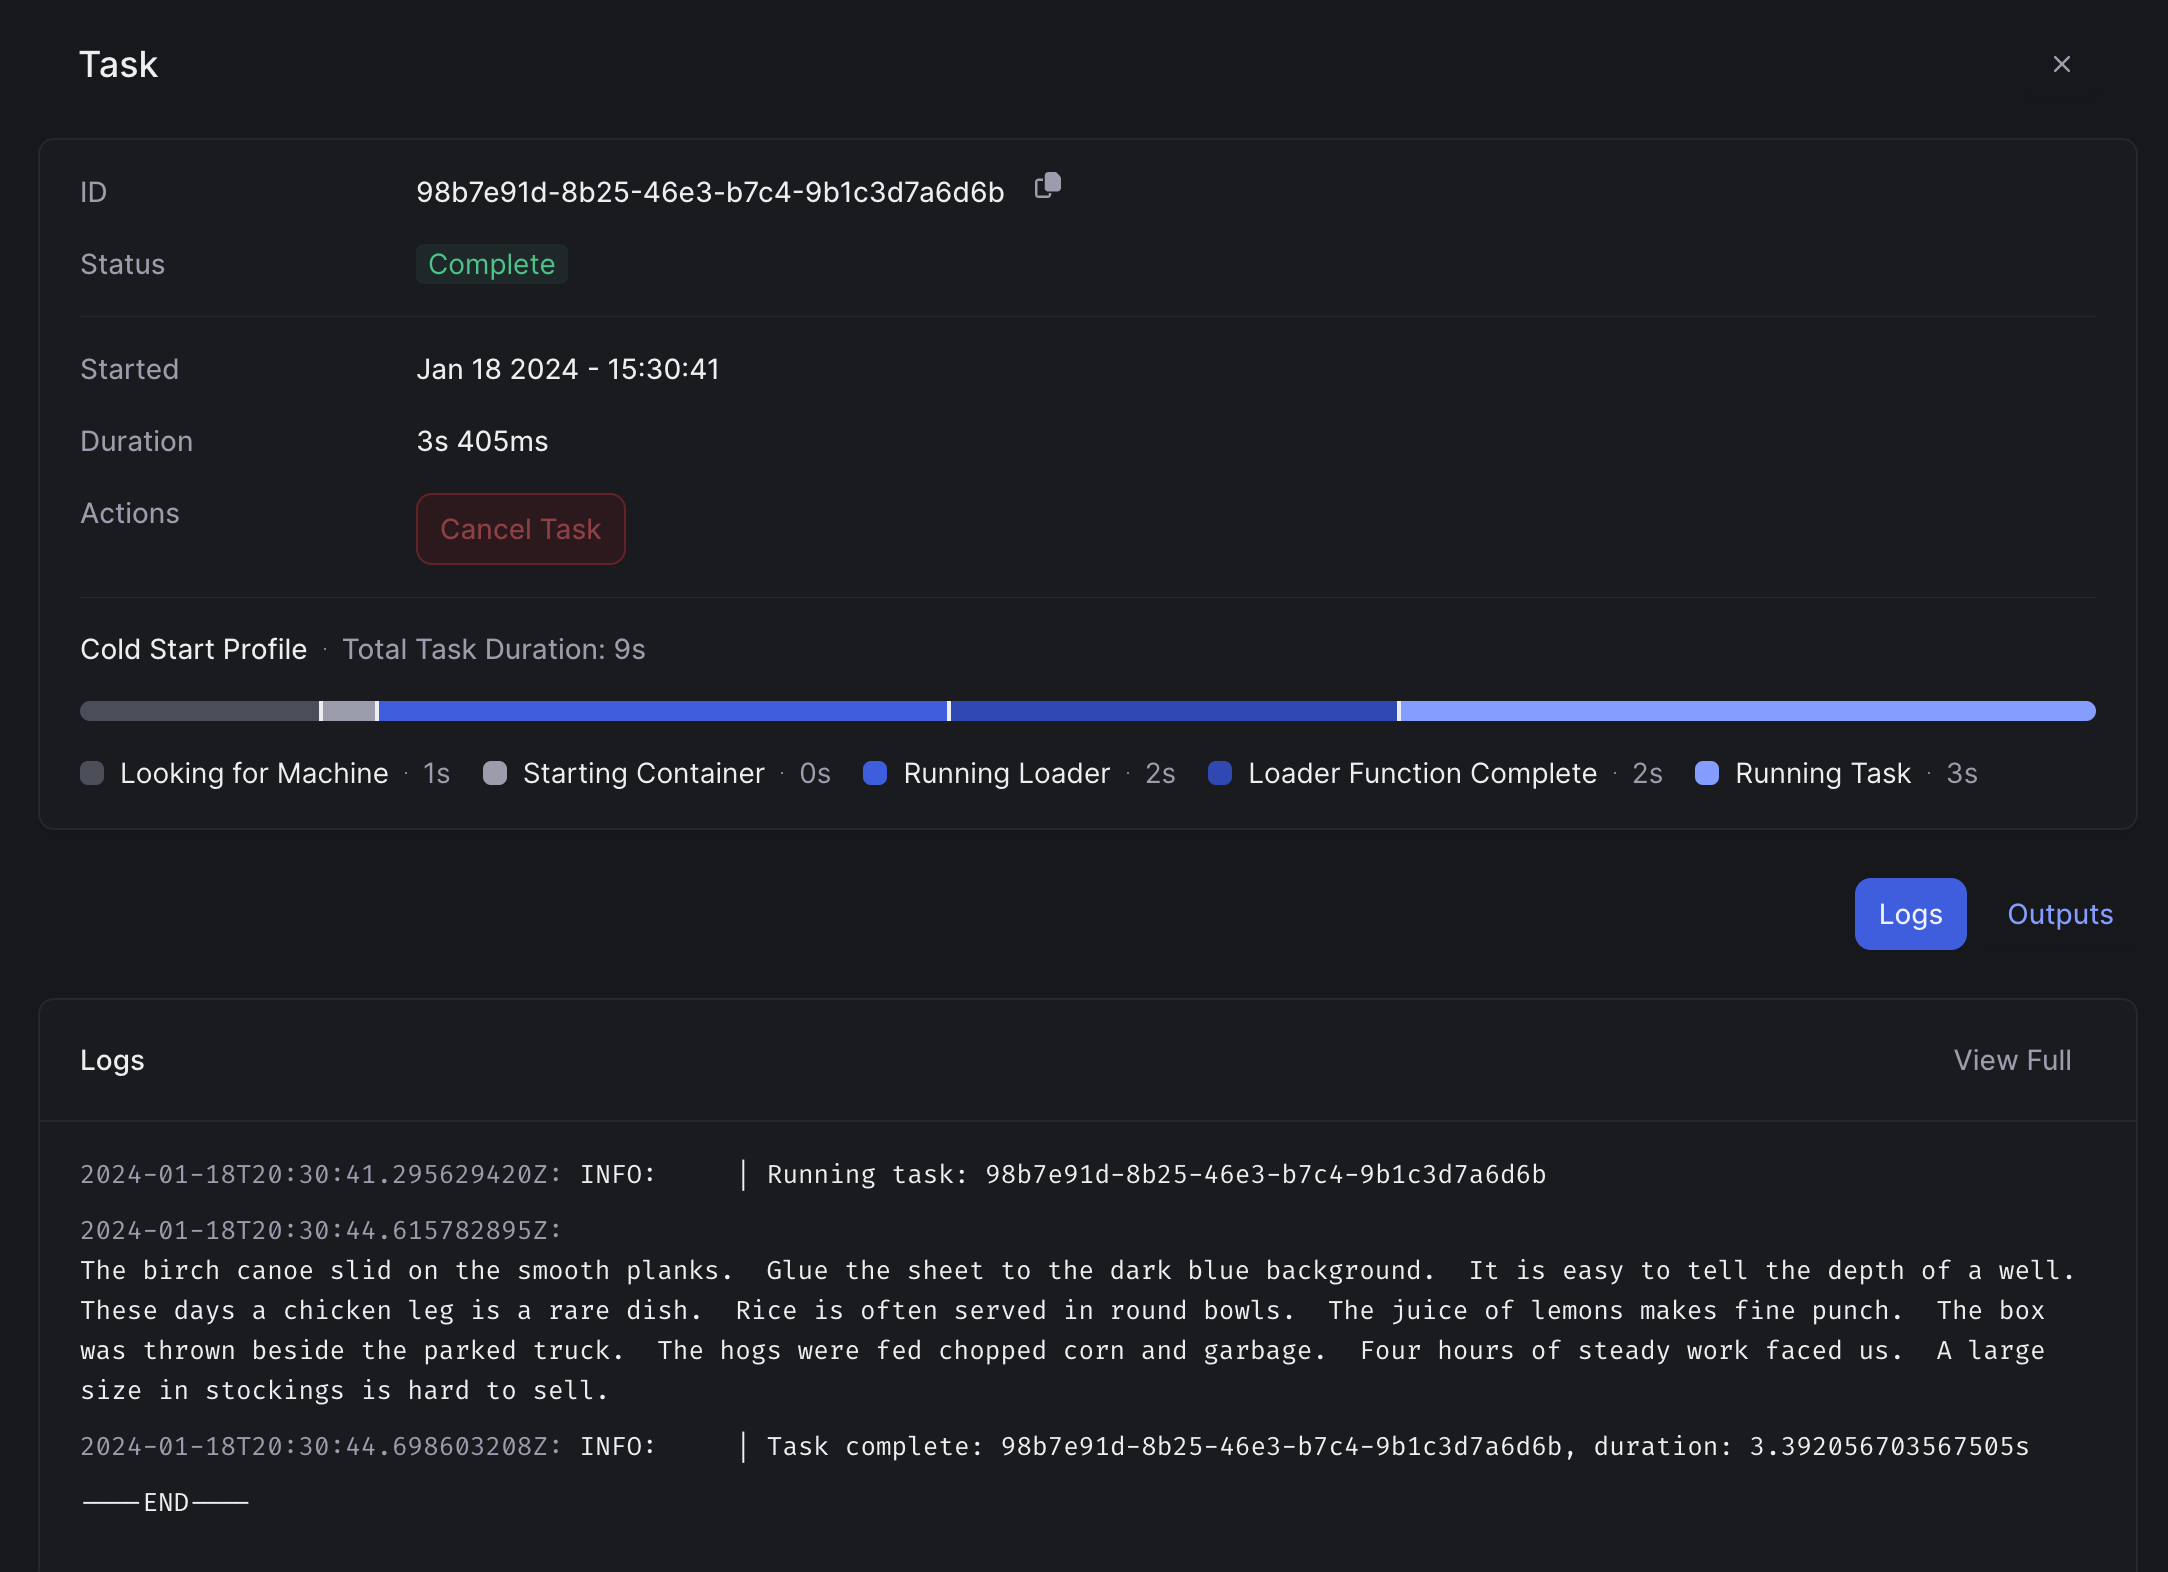
Transcription with Faster Whisper
A step-by-step guide to deploying Faster Whisper on a cloud GPU
Eli Mernit
Serverless GPUs for AI Inference and Training
Learn how to use serverless GPUs for fast and affordable AI inference and training, including comparisons between the top providers and strategies to optimize cold boot.
Eli Mernit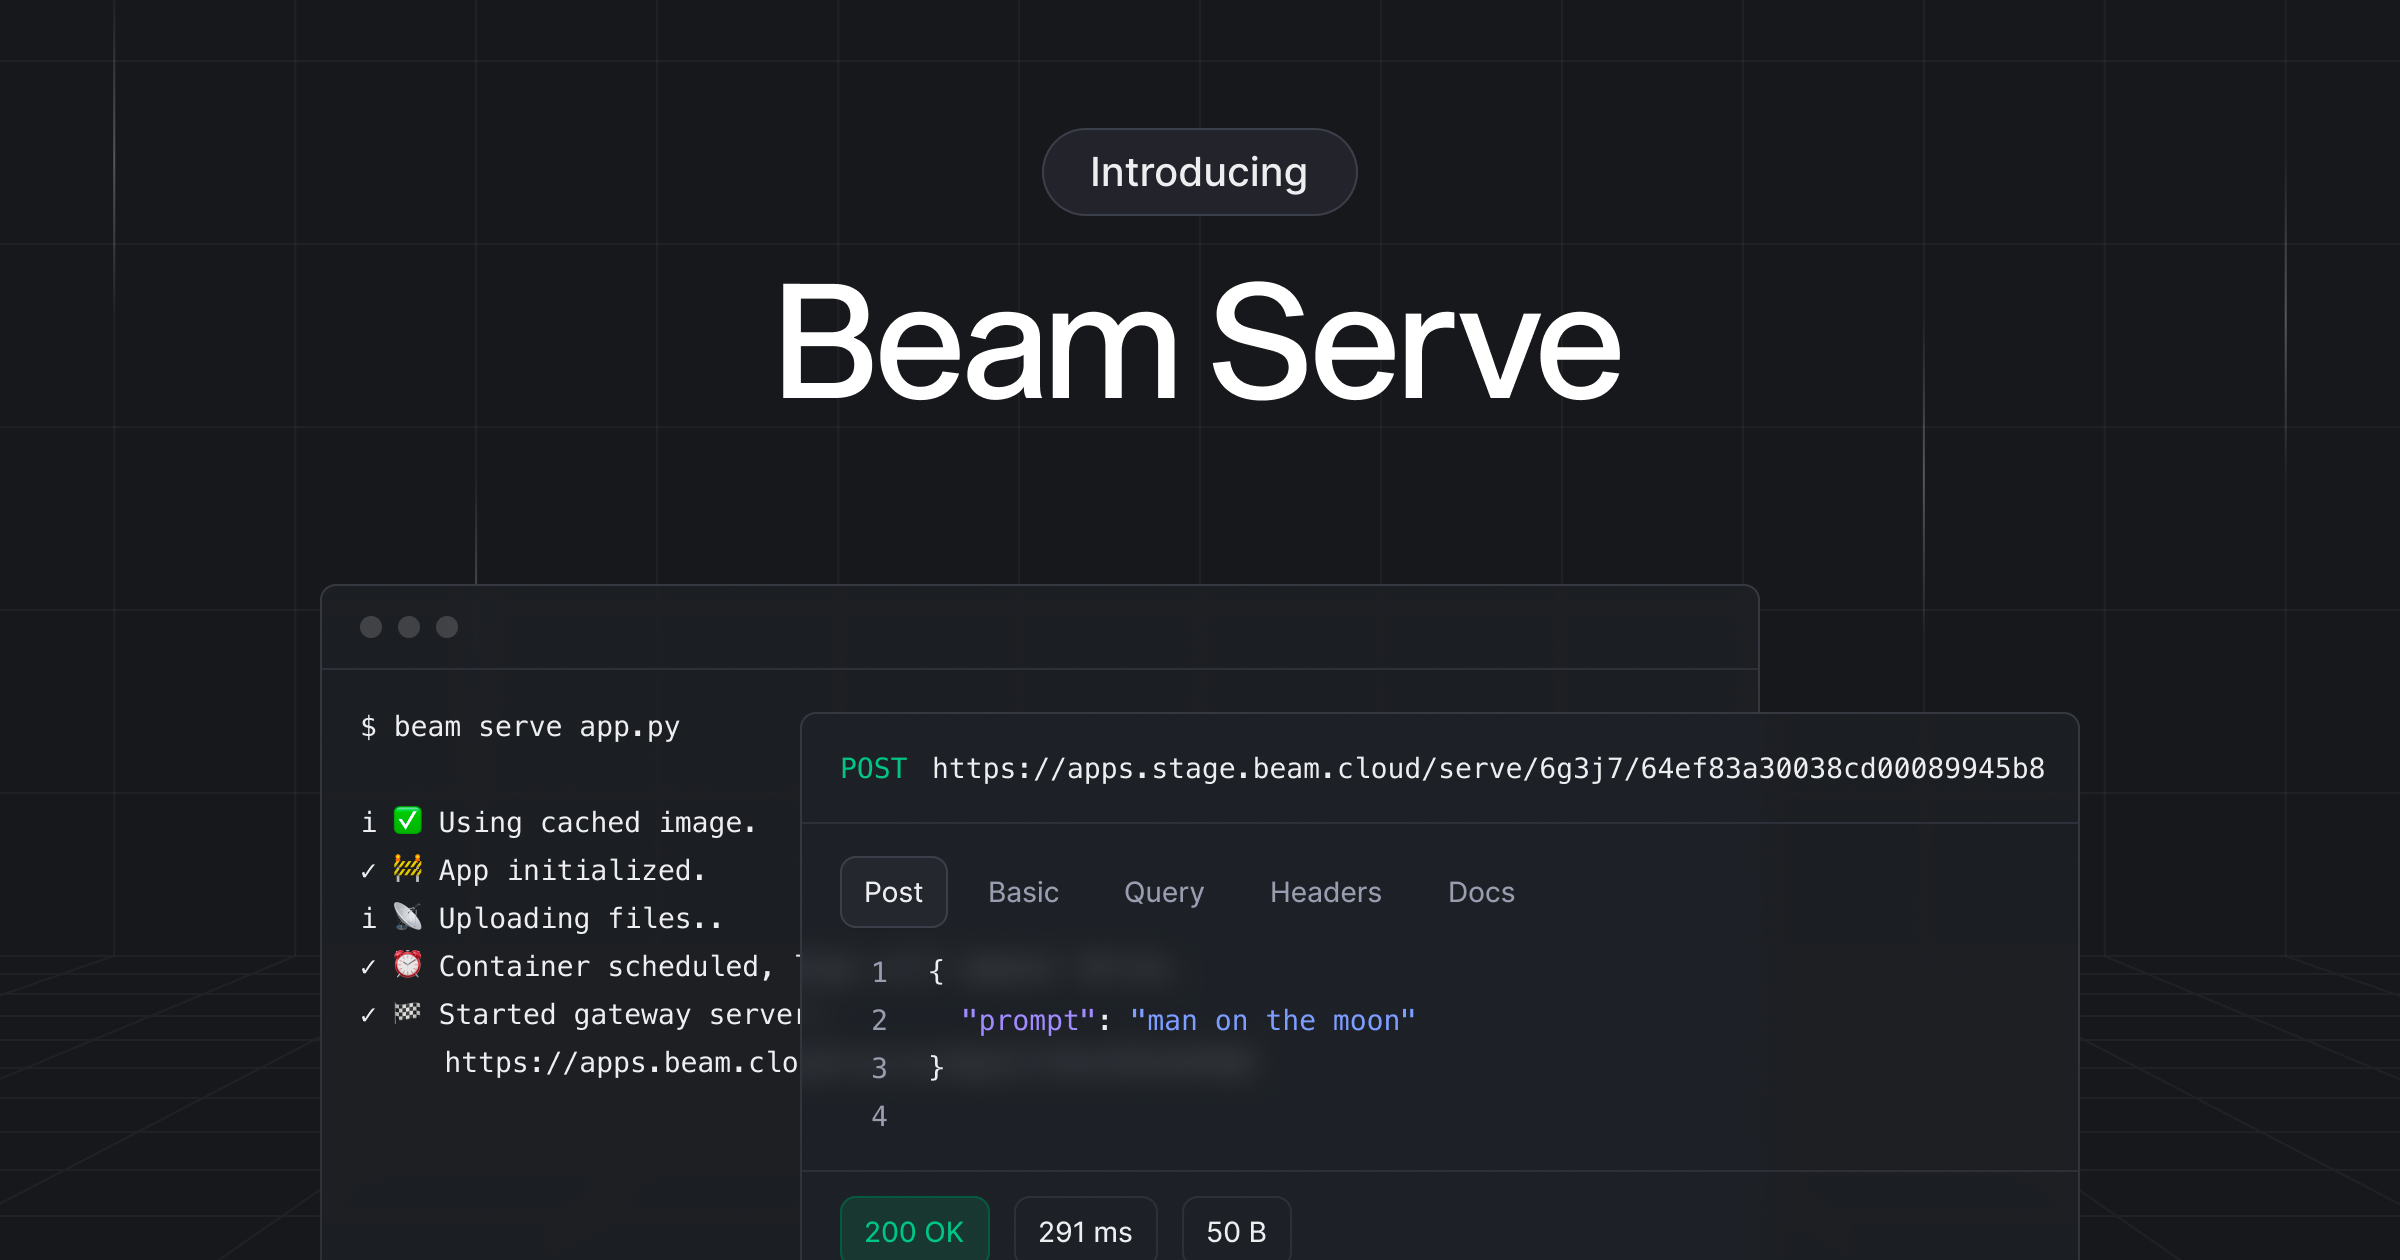
Introducing: Beam Preview Environments
Today, we’re releasing Beam Serve. It improves the debugging experience of Beam apps, and also enables you to run Python functions as ephemeral APIs.
 John Marshall
Why We’re Not Using Kubernetes to Scale Our GPU Workloads
While we initially tried Kubernetes-based autoscaling for our system, we realized that CPU and memory-based autoscaling strategies didn’t take into account the actual behavior of an application.
Eli Mernit
Better Abstractions for the Cloud
In 2017, I was working at a data startup. We had a pipeline that was running on several large EC2 instances, each of which had a bunch of celery workers eating through a queue of files to process.
Luke Lombardi
Developing a Serverless Stable Diffusion API
Stable Diffusion has unlocked a range of entrepreneurial projects, from Avatars to Magical AI Art Tools. However, there's still a high cost in setting up the dev environment required to iterate on ML models using GPUs.
Eli MernitStart shipping on infra
you won’t outgrow.
Run sandboxes and GPU workloads on your cloud, and scale out to ours when you need to. No infra to manage.